
How do you find useful information across onion services without relying on scattered links or broad, surface-web results? A dedicated excavator search engine is designed to index and retrieve pages associated with those services, helping users search a specialized environment through more focused queries.
That focus can make research more manageable, but it does not make the dark web automatically private, trustworthy, or safe. Understanding how indexing works, where results fall short, and how to verify a destination helps curious users and researchers make more informed decisions.
Key Takeaways
- A dedicated search engine can narrow onion searches but cannot guarantee that a result is safe or current.
- Verify an onion address through independent, trusted channels before visiting it.
- Use focused queries and careful source checks to reduce irrelevant or misleading results.
- Protect your identity and device with updated software and cautious browsing practices.
How does an excavator search engine find onion pages?
An onion search engine generally discovers pages through links it can access, then processes their text and metadata into a searchable index. Unlike a directory that depends on a person maintaining a list, an index can return pages based on matching terms, although coverage depends on what the crawler can reach and how often it revisits a service.
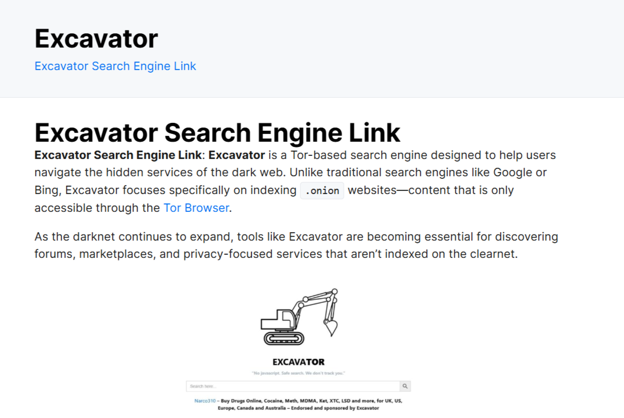
Search results are therefore snapshots, not a live inventory of everything online. Services may move, go offline, restrict access, or block automated crawlers, so an excavator search engine link found in results may be stale or point to a page whose content has changed since indexing.
What makes a dedicated search engine useful for research?
A specialized index can reduce irrelevant results by focusing on a narrower set of services and content than a general-purpose search engine. This is useful when a researcher has a precise subject, terminology, or document type in mind, and wants to compare several sources rather than follow a chain of unverified recommendations.

Query design matters: start with a distinctive phrase, then try a synonym or a narrower term if the first results are noisy. For example, a researcher studying privacy terminology might search for an exact technical phrase and then compare results for its common abbreviation; the contrast can expose whether a page uses precise language or merely repeats popular keywords.
A search result is a lead to assess, not proof that a page is accurate, safe, or endorsed.
How can you assess an excavator search result before opening it?
Check the result's title and snippet for a clear connection to your query, and treat sensational wording or promises of guaranteed access with skepticism. Compare the displayed address against a separately obtained reference when possible, because a convincing page title does not establish that an onion address is authentic.
Researchers who need extra context may consult excavator dark web search engine alongside the search listing, since independent details can help identify a mismatch before a visit. Keep research notes that record the query, date checked, and reason a result appears relevant; this makes it easier to revisit uncertain findings without treating memory as verification.
What practical steps make dark web searching more controlled?
Separate discovery from interaction: first assess a result using its visible information, then decide whether opening it is necessary for the research question. Use the Tor Browser from its official distribution channel, keep it updated, avoid downloading unknown files, and do not enter personal credentials on unfamiliar services.
For a simple workflow, suppose a researcher needs to find public discussion of a narrow technical phrase. They can search that phrase, record a small set of relevant results, compare the snippets and addresses, verify a candidate address independently, and open only the most relevant page in a controlled browsing session; if it fails verification, they stop rather than chasing substitutes.
- Define the research question and choose a specific starting phrase.
- Review result titles, snippets, and visible addresses before visiting.
- Check a candidate address against an independent, trusted reference.
- Open only what is necessary, and avoid unknown downloads or sign-ins.
- Record what was checked and discard results that cannot be verified.
This sequence does not eliminate risk, but it limits unnecessary exposure and creates a repeatable method. If you are comparing tools, excavator search engine onion may offer a useful point of reference, provided you check its claims and address through a separate channel rather than assuming that any listing is current.
When should you choose another search method?
A dedicated excavator dark web search engine is not the right tool for every research task. If you need information from established publications, official records, or academic material, use the relevant public databases first; their provenance and editorial processes are often easier to assess than an anonymous onion result.
Even within onion research, search engines can miss unlinked pages, content behind access controls, and material that changes frequently. When an answer depends on authenticity or completeness, corroborate it with independent sources and state the limits of what the search could retrieve, rather than presenting an index result as a definitive record.
People investigating an excavator onion search engine should also distinguish a search service from the pages it indexes. A service's interface may help find content, but it cannot certify every destination; consult Excavator Link for additional context only when its identity and relevance can be checked independently.
Frequently Asked Questions
Can an excavator search engine show every onion service?
No. It can return only pages its crawler discovers and indexes, and services may be unreachable, unlinked, or restricted.
Does an excavator search engine guarantee that a result is safe?
No. Search engines retrieve pages; they do not guarantee that a destination is trustworthy or harmless. Verify addresses independently and avoid unknown downloads.
Why does an excavator search result lead to an offline page?
Onion services can change addresses, go offline, or block crawlers after a page is indexed. Treat the listing as potentially outdated and do not rely on unverified replacement links.
Should I use a dedicated engine or a regular search engine?
Use a dedicated engine when the research specifically concerns indexed onion content. For public sources, official documents, and mainstream reporting, regular search tools or specialized databases are usually more appropriate.
Can I open an onion result without downloading anything?
Often you can view a page without downloading files, but browsing still carries risk. Keep the browser current, avoid personal logins, and leave if a page prompts you to install software or open an unfamiliar file.
How can I tell whether an excavator search engine link is genuine?
Compare the address with information from an independent, trusted source rather than trusting a search listing alone. Do not enter sensitive information if the service's identity remains uncertain.